There are some limitations with STRING_SPLIT that could be overcome, but the cleanest solution might be to add a new function altogether.
There are some limitations with STRING_SPLIT that could be overcome, but the cleanest solution might be to add a new function altogether.
Find out about the replacement I wrote for the undocumented, unsupported, and ill-advised system procedure, sp_MSforeachdb.
Updated in 2020 with a few new entries, this is a fairly comprehensive list of the reasons behind various 18456 error messages.
See two ways you can make the relevant data in the system_health session last longer and not get drowned out by noise.
Access the system_health file target without tedious string parsing gymnastics.
This series shows how I determine the amount of data distributed across indexes, files, filegroups, and partitions.
Dig into an intermittent stack dump involving an aggregate query against a heap with a LOB column.
Discover some undocumented or unsupported behavior you might not even realize you're relying on.
See a quick T-SQL script for determining how often Cinco de Mayo falls on Taco Tuesday.
I continue a series where I dig into how data is distributed across indexes, files, and filegroups.

I talk about a recent change where I started turning on indirect checkpoints across all user databases.
I finish up my series on replacing the default trace with views to simplify consumption and a caveat about reports in SSMS.
See the stored procedure I wrote to help me put all file, filegroup, and index information in one place.
I continue my series on replacing the default trace with a more efficient and more complete Extended Events session.

See a quick example where plan shape can cause errors that really shouldn't happen.
In this tip, see ways you can change how a function is called without having to modify all calling code at the same time.
Need to get data, log, or bak files into your container's file system? See how, with docker cp.

I start a series explaining how I evaluated the default trace and decided to replace it with a slimmer Extended Events session across all of production.

See how you can use Extended Events to find your worst performing checkpoints.

In this tip, I talk about a concerning behavior in a dynamic management function.
I continue my series on large table compression with results from row and page compression as well as a process involving scheduler manipulation.

In this tip, I show how soft deletes and a filtered index can help minimize the cost of ghost records in an Availability Group.
I continue my series on investigating compression for a 1TB table, honing in on clustered columnstore and partitioning.
I show how I tried to chase down a very unexpected issue with SQL Server metadata. Spoiler: it didn't end the way I thought it would.
Discover a simple way to keep your filtered indexes effective – even under forced parameterization.
Conventional wisdom has suggested that deletes should be batched, but in some cases this can actually take a lot longer.
See how to generate a set of scripts that will delete rows from dependent tables and show you how many rows will be deleted from each.
For this month's T-SQL Tuesday, I talk about an incident where I've changed my mind about something I was previously pretty stubborn about.
Find out how to use dynamic SQL to quickly generate metadata queries to pull attributes for all columns across a database or even a set of databases.
Forced Parameterization can be a useful setting to tune workloads, but this can work against you if you're also using filtered indexes.
Give your Docker containers meaningful port numbers to avoid confusion, especially when presenting or giving demos.
Originally published in 2009, I updated this in 2019 with an example showing an effect on the plan cache.
Did you know that not all characters can be used as the separator for STRING_SPLIT?
Read about an approach to partitioning a result set without the performance impact of NTILE.
See how to work around the lack of an ALTER TYPE command.
Discover some of the new information SQL Server keeps adding to help us troubleshoot query plans.
One of the biggest downsides of using SQL Server Management Studio as an interactive query tool is the limit on text/grid output. SSMS 18.2 fixes that!
In this tip, you'll see the metadata queries that will make it possible to discover which integer-based columns could be made smaller (without any loss of data).
I explain four conventions I always follow when writing T-SQL queries.
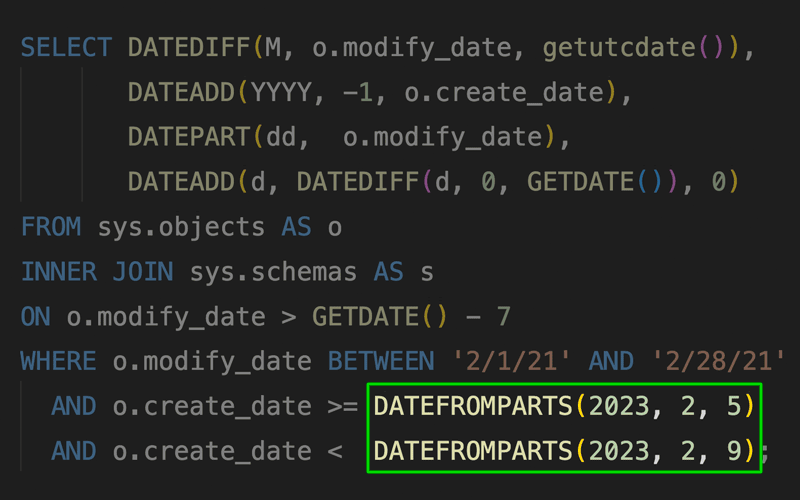
See how you can use new functions like DATEFROMPARTS to simplify otherwise really cryptic methods to obtain key dates (like the first day of the current month).
Get a first-hand look at some of the ways NOLOCK can produce incorrect data.
Aaron Bertrand talks about a few of the things that he wished he had learned earlier on.
This tip shows how powerful the CASE expression is, and some of the nuances in its behavior.
See one approach to collecting extended properties information across all of the databases on a server.
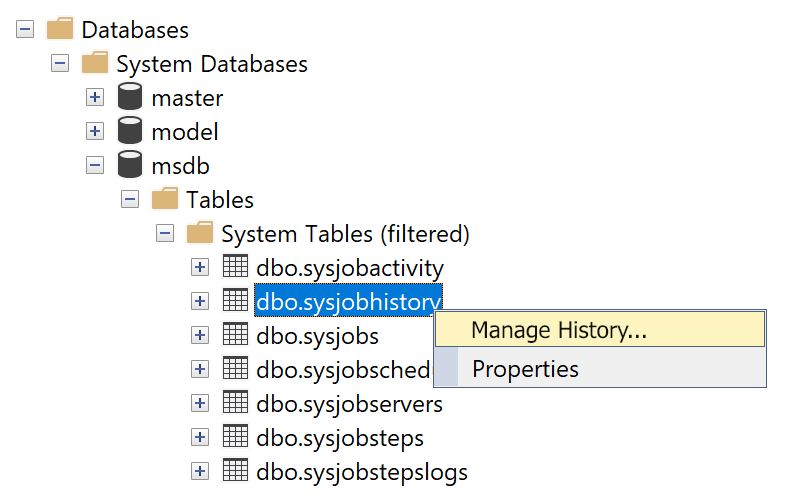
Break free from the limitations of history retention and take control at the job or even step level.
In part 2 of this series, we add another way to further isolate multiple threads of a bulk import process.
In the first of a 2-part series, see how you can easily reduce contention between multiple bulk import threads.
This tip shows a neat trick with CROSS APPLY that lets your metadata queries ignore columns that don't exist yet.